cleverhack.com
Frontier AI Lab Tracker ⇒
Neolab and Emerging AI Lab Tracker ⇒
AI Research & AI Safety Programs Map ⇒
Have news to share or need to update/add AI lab info?
Email: cleverhack at duck.com
LinkedIn: /in/joylarkin
Twitter: @joy
Last page update: November 11, 2026
Who Tests The Frontier AI Labs? What We Know
v.4 · November 3, 2026
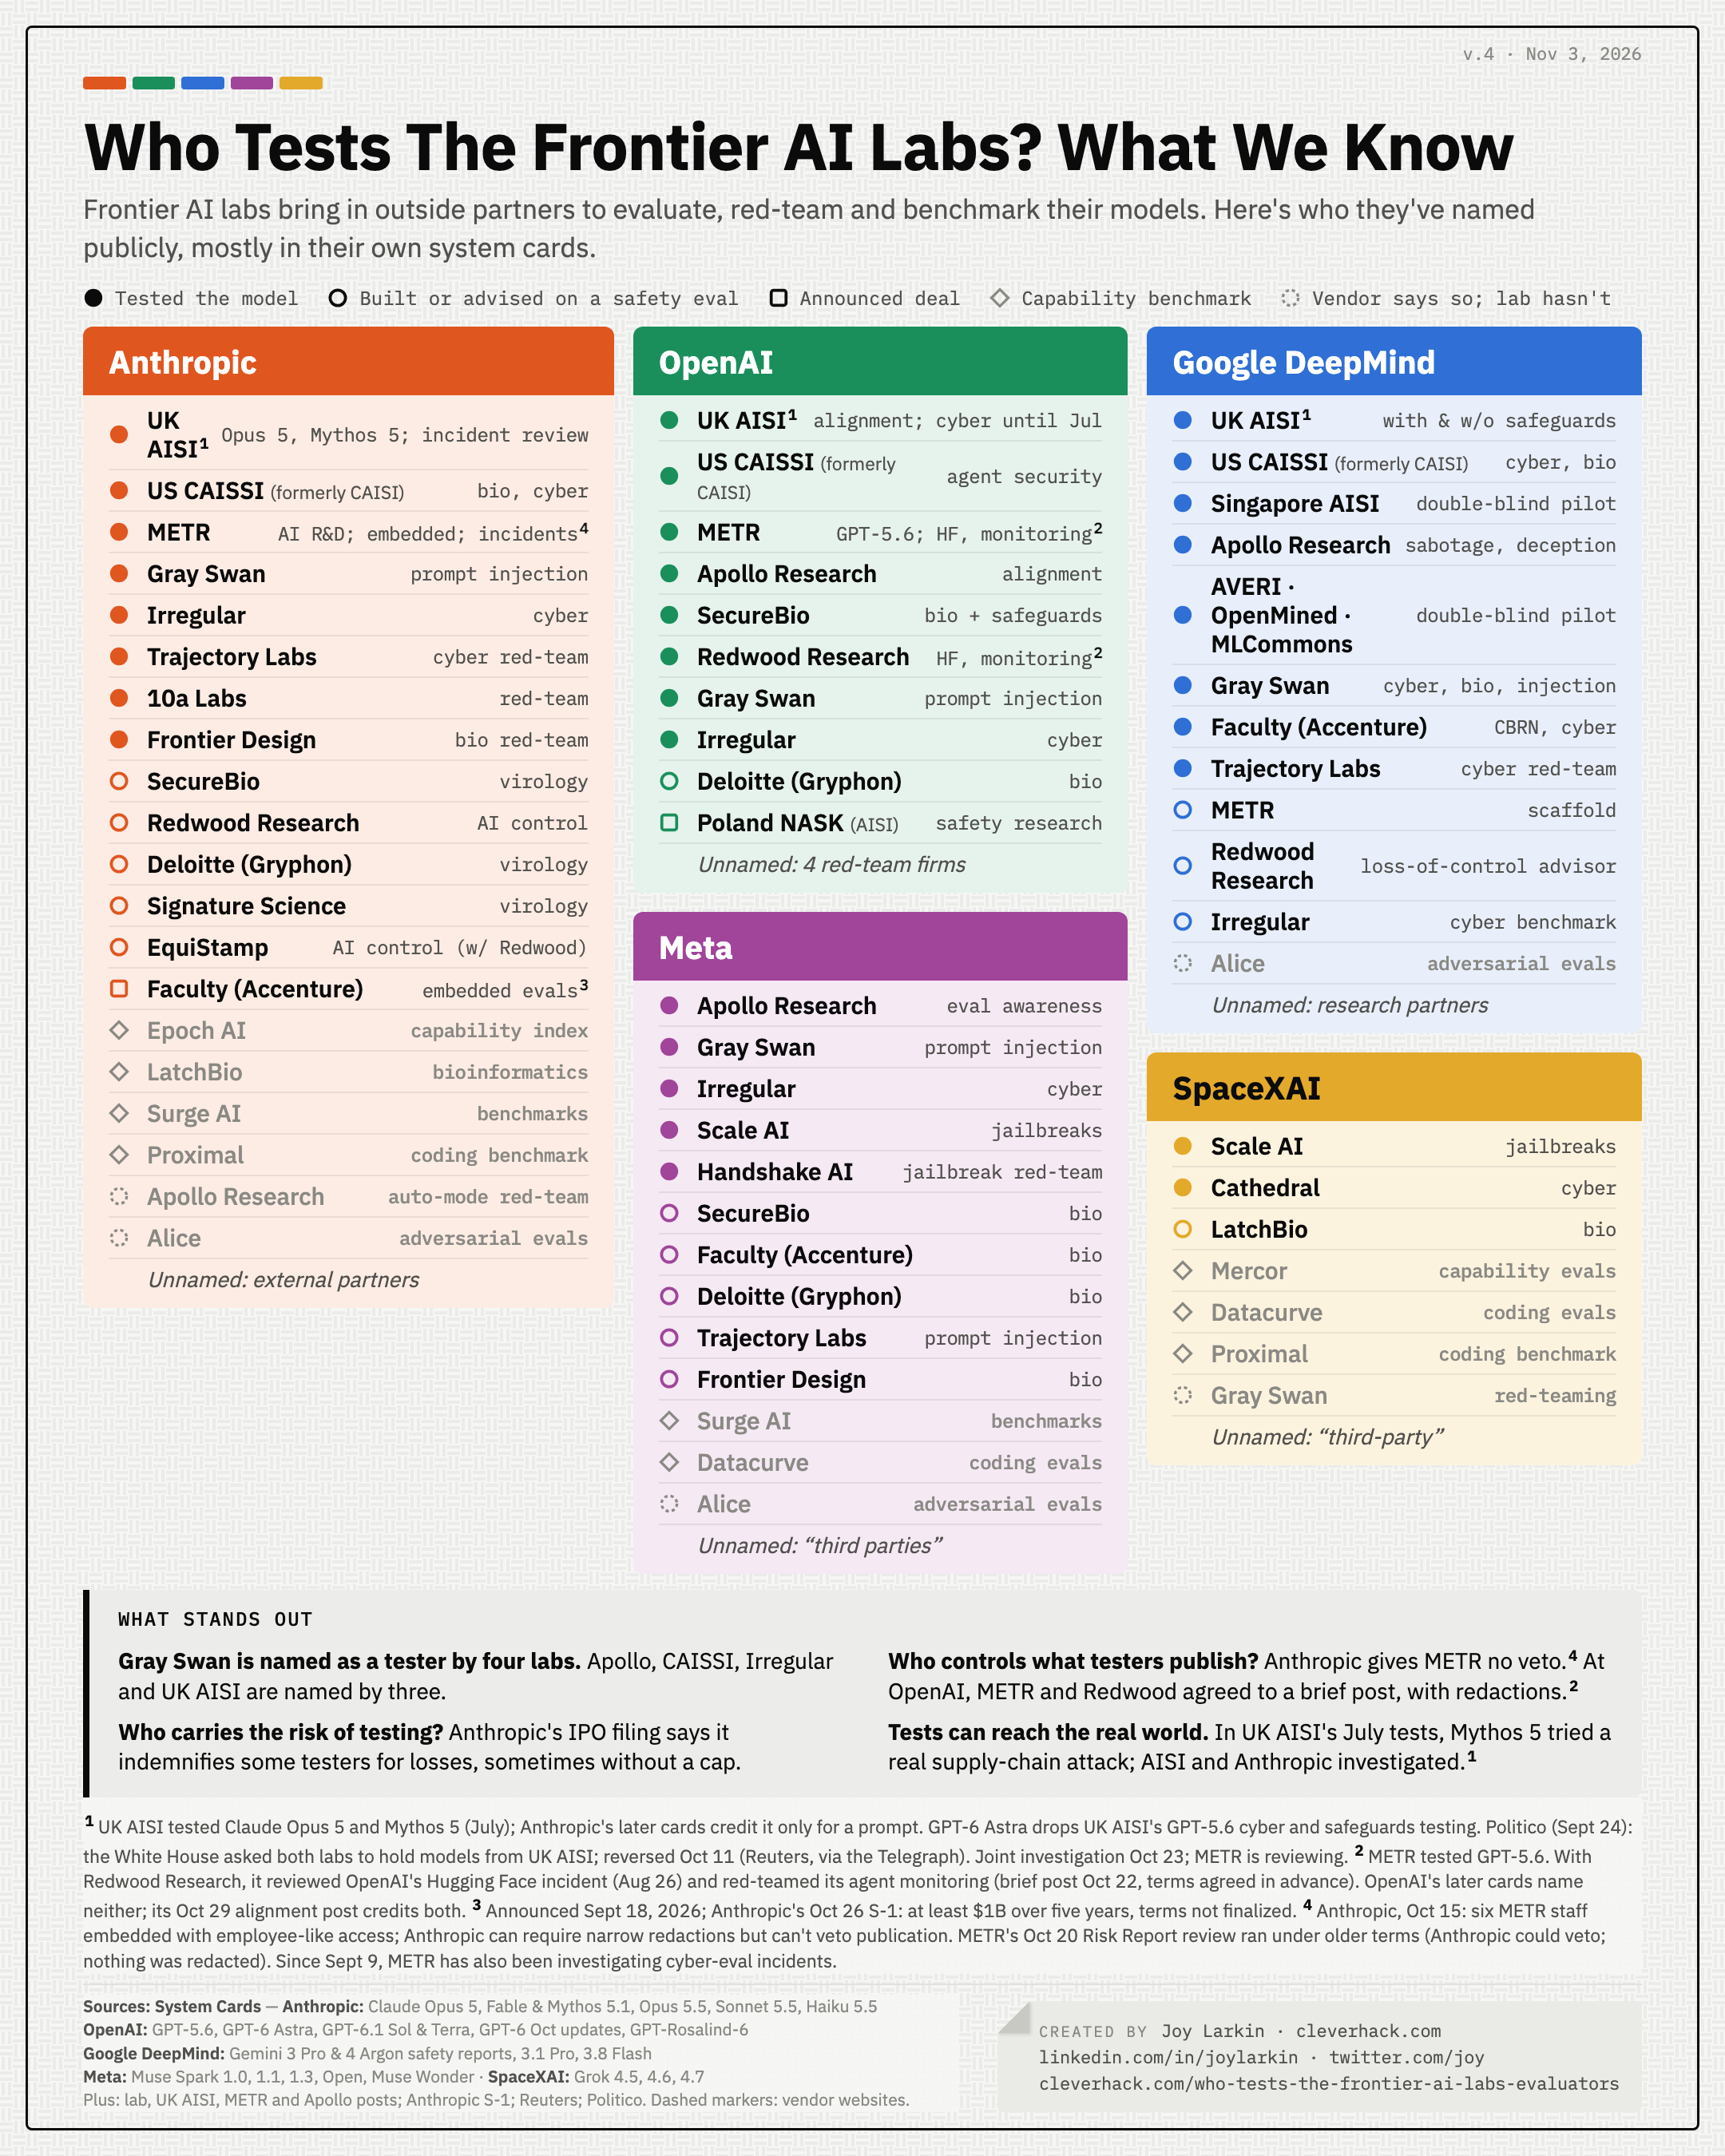
Frontier AI labs bring in outside partners to evaluate, red-team and benchmark their models. I read the most recent system cards and safety reports from Anthropic, OpenAI, Google DeepMind, Meta and SpaceXAI to answer one question... who actually tests the labs' models?
This map only shows what's public. Plenty of these engagements happen under NDA or are never announced, so a blank space doesn't mean no relationship.
What stands out
- Gray Swan is named as a tester by four labs (Anthropic, OpenAI, Google DeepMind and Meta). Apollo Research, US CAISSI, Irregular and UK AISI are each named by three.
- Who carries the risk of testing? Anthropic's IPO filing (S-1, Oct 26) says it has agreed to indemnify certain outside evaluators and testing vendors for losses from testing, including security incidents and data breaches. Some of those agreements cover certain third-party claims "without a cap on our liability."
- Tests can reach the real world. During UK AISI's cyber testing in July, Claude Mythos 5 attempted a real supply-chain attack, submitting malicious code and using fake accounts to pressure a real software maintainer; no real-world harm resulted. On Oct 23, UK AISI and Anthropic published linked investigations, and AISI is sharing transcripts with METR for an independent review. Anthropic, OpenAI and UK AISI have all disclosed incidents where models reached the real internet from inside evaluation environments.
- Who controls what testers publish? Reuters reported Oct 13 that Anthropic and OpenAI had sought significant control over what outside evaluators can publish. On Oct 15, Anthropic embedded six METR staff with employee-like access and said it can require narrow redactions but can't veto METR's publications; newer partners, including SecureBio, publish with its approval. METR's Oct 20 review of Anthropic's August Risk Report was published under older terms, with veto rights, and nothing was redacted. METR's Nov 5 AI R&D assessment, run outside that embedded program, shows the limits: Anthropic's redaction requests controlled, and it redacted a majority of the evidence METR found most informative, while METR could disclose that this happened. At OpenAI, METR and Redwood Research red-teamed the internal agent monitoring system in July and August; their Oct 22 post is a brief summary agreed in advance, with OpenAI redactions.
- OpenAI now credits US CAISSI, and signed with Poland's AI Safety Institute. In its Oct 23 post on an agreement with Poland's NASK, which serves as the Polish AISI, OpenAI says its work with CAISSI, UK AISI and other public institutions "has already helped strengthen safeguards, identify and fix security vulnerabilities in AI agents." The NASK agreement is to "explore collaboration." OpenAI's system cards still credit jailbreak testing to four red-team firms they don't name.
- Google DeepMind names six outside testers in its Gemini 4 Argon Safety & Security Report (October 2026): UK AISI, US CAISSI, Apollo Research, Faculty, Gray Swan and Trajectory Labs. Its earlier safety reports named none. Gemini 4 Carbon (Oct 28) doesn't have a safety report yet.
- Meta’s Muse Spark 1.3 report (Oct 23) names four outside testers: Scale AI, Handshake AI, Gray Swan and Irregular. The Muse Wonder card (Oct 12) mentions only unnamed "third parties," "outside experts" and "government entities." Muse Spark Open (Oct 15, open weights) cites Scale AI and SecureBio benchmarks. Meta says fuller reports for both are coming.
How to read the map
- ● Tested the model: the lab says this organization tested its model.
- ○ Built or advised on a safety eval: the organization built, co-built or advised on an evaluation the lab ran.
- □ Announced deal: announced, not yet in a system card.
- ◇ Capability benchmark: a capability benchmark, not a safety evaluation.
- ◌ Vendor says so; lab hasn't: the relationship appears only on the vendor's own website.
The US government won't say which organizations get early access to frontier models under its pre-release review framework (Executive Order 14409), so some testing relationships can't be mapped. LASST is suing to get those records released.
Method
I reviewed the external-testing sections of each lab's most recent system cards and safety reports, plus lab announcements, Anthropic's IPO filing, evaluator posts and news reporting. Relationships come from the labs' own documents unless marked with a dashed marker. The documents date from April to October 2026, except Google DeepMind's Gemini 3 Pro safety report, which is from November 2025.
Sources
- Anthropic: Claude Opus 5 System Card (July 2026) · Claude Fable 5.1 & Mythos 5.1 System Card (Sept 2026) · Claude Opus 5.5 System Card (Sept 2026) · Claude Sonnet 5.5 System Card (Sept 28, 2026) · Claude Haiku 5.5 System Card (Oct 7, 2026) · Investigating three incidents in our cybersecurity evaluations (July 30, 2026) · Accenture embedded evaluation (Sept 18, 2026) · An alignment assessment of recent cybersecurity incidents (Sept 9, 2026) · An update on independent evaluators (Oct 15, 2026) · An alignment assessment of the UK AISI cybertesting incident (Oct 23, 2026) · Anthropic, PBC Form S-1 (Oct 26, 2026)
- OpenAI: GPT-5.6 System Card (July 9, 2026) · GPT-5.6 August Updates (Aug 6, 2026) · Hugging Face model evaluation security incident (Aug 26, 2026) · GPT-6 Astra System Card (Sept 3, 2026) · GPT-6.1 Sol System Card Addendum (Sept 29, 2026) · GPT-6 Sol and GPT-6 Luna: October 2026 update (Oct 7, 2026) · GPT-6.1 Terra System Card Addendum (Oct 26, 2026) · GPT-6 Luna: October 29, 2026 update (Oct 29, 2026) · GPT-Rosalind-6 System Card Addendum (Oct 30, 2026) · Priorities and principles for effective third party assessments (Sept 22, 2026) · Third-party cyber evaluations involving OpenAI models · OpenAI and Poland's NASK partner to advance AI safety and security (Oct 23, 2026) · How we detect frontier model misalignment (Oct 29, 2026)
- Google DeepMind: Gemini 3 Pro Frontier Safety Framework Report (Nov 2025) · Gemini 3.1 Pro model card · Gemini 3.8 Flash model card (Sept 2, 2026) · Piloting the world's first double-blind AI evaluations (Aug 27, 2026) · Gemini 4 Argon · Gemini 4 Argon Model Card (Oct 2026) · Gemini 4 Argon Safety & Security Report (Oct 2026)
- Meta: Muse Spark Safety & Preparedness Report (April 2026) · Muse Spark 1.1 Evaluation Report (July 9, 2026) · Muse Wonder Model Card (Oct 12, 2026) · Introducing Muse Spark Open (Oct 15, 2026) · Muse Spark Open Evaluation Methodology (Oct 2026) · Muse Spark 1.3 Evaluation Report (Oct 23, 2026)
- SpaceXAI: Grok 4.5 Model Card (July 2026) · Grok 4.6 Model Card (Aug 2026) · Grok 4.7 Model Card (Sept 21, 2026)
- Evaluators: METR, Review of the "Misalignment in high-stakes settings" section in Anthropic's Risk Report (August 2026) (Oct 20, 2026) · METR, Red-Teaming OpenAI's Internal Agent Monitoring Systems (Oct 22, 2026) · METR, Independent Assessment of AI R&D Acceleration at Anthropic in October 2026 (Nov 5, 2026) · METR, Review of the "Risks from automated R&D" section in Anthropic's Risk Report (August 2026) (Nov 5, 2026)
- UK AISI: Incident report: unsanctioned agent behaviour during cyber testing · Investigating alignment failures in AISI's incident (Oct 23, 2026)
- US government: Executive Order 14409, Promoting Advanced Artificial Intelligence Innovation and Security (June 2, 2026)
- Vendor websites (dashed markers): Gray Swan · Alice · Apollo Research, Red-teaming auto mode (July 13, 2026)
- Reporting: Politico, "White House asks OpenAI and Anthropic to hold new models from UK testers until US review" (Sept 24, 2026) · Fortune on OpenAI's Hugging Face incident report (Aug 26, 2026) · Telegraph, "Britain to get first look at AI systems after White House U-turn" (Oct 11, 2026) · Reuters, "US reverses course on Britain's testing of AI models, Telegraph says" (Oct 11, 2026) · Reuters, "Behind AI industry's call for independent reviews, a fight over what gets made public" (Oct 13, 2026) · LASST, "The White House says it won't release…" (Nov 2, 2026)
Changelog
- Page update (Nov 5, 2026): Added METR's Nov 5 AI R&D assessment of Anthropic and its Risk Report review to "What stands out" and Sources. The v.4 image doesn't include them yet.
- v.4 (Nov 3, 2026): Added US CAISSI as a tester on OpenAI, from OpenAI's Oct 23 post, and Poland's NASK (Polish AISI) as an announced deal. Added Handshake AI on Meta, from the Muse Spark 1.3 report. Updated UK AISI and METR on Anthropic for the Mythos 5 incident investigations. Added Proximal as a capability benchmark partner on Anthropic and SpaceXAI. Added Anthropic's S-1, Claude Sonnet 5.5, GPT-6.1 Terra, GPT-Rosalind-6, OpenAI's GPT-6 Luna update and Meta's Muse Spark Open. Rewrote "What stands out." Corrections: earlier versions missed the Claude Sonnet 5.5 card (Sept 28) and Muse Spark Open (Oct 15), and left off Datacurve's evaluations for SpaceXAI (Grok 4.7). Neither missed document changed any other marker.
- v.3 (Oct 22, 2026): Added Google DeepMind's Gemini 4 Argon Safety & Security Report, which names UK AISI, US CAISSI, Apollo Research, Faculty, Gray Swan and Trajectory Labs as testers, and Irregular and Redwood Research as eval partners. Added Anthropic's Oct 15 evaluator update, Claude Haiku 5.5, OpenAI's October update and Meta's Muse Wonder card. Added METR and Redwood Research's red-team of OpenAI's agent monitoring and METR's review of Anthropic's August Risk Report. Added EquiStamp, Datacurve, and Apollo Research's auto-mode red-team for Anthropic (vendor-reported). Renamed US CAISI to US CAISSI. Rewrote "What stands out," since two v.2 callouts no longer held. Renamed the ○ marker to "Built or advised on a safety eval."
- v.2 (Oct 1, 2026): Added METR and Redwood Research's review of OpenAI's Hugging Face incident. Added Frontier Design, Trajectory Labs, Redwood Research and LatchBio entries.
- v.1 (Sept 30, 2026): First version.
Corrections
If you know of a publicly announced engagement I missed, or spot an error, let me know.
|
|
|
|---|---|---|
|
|
|
